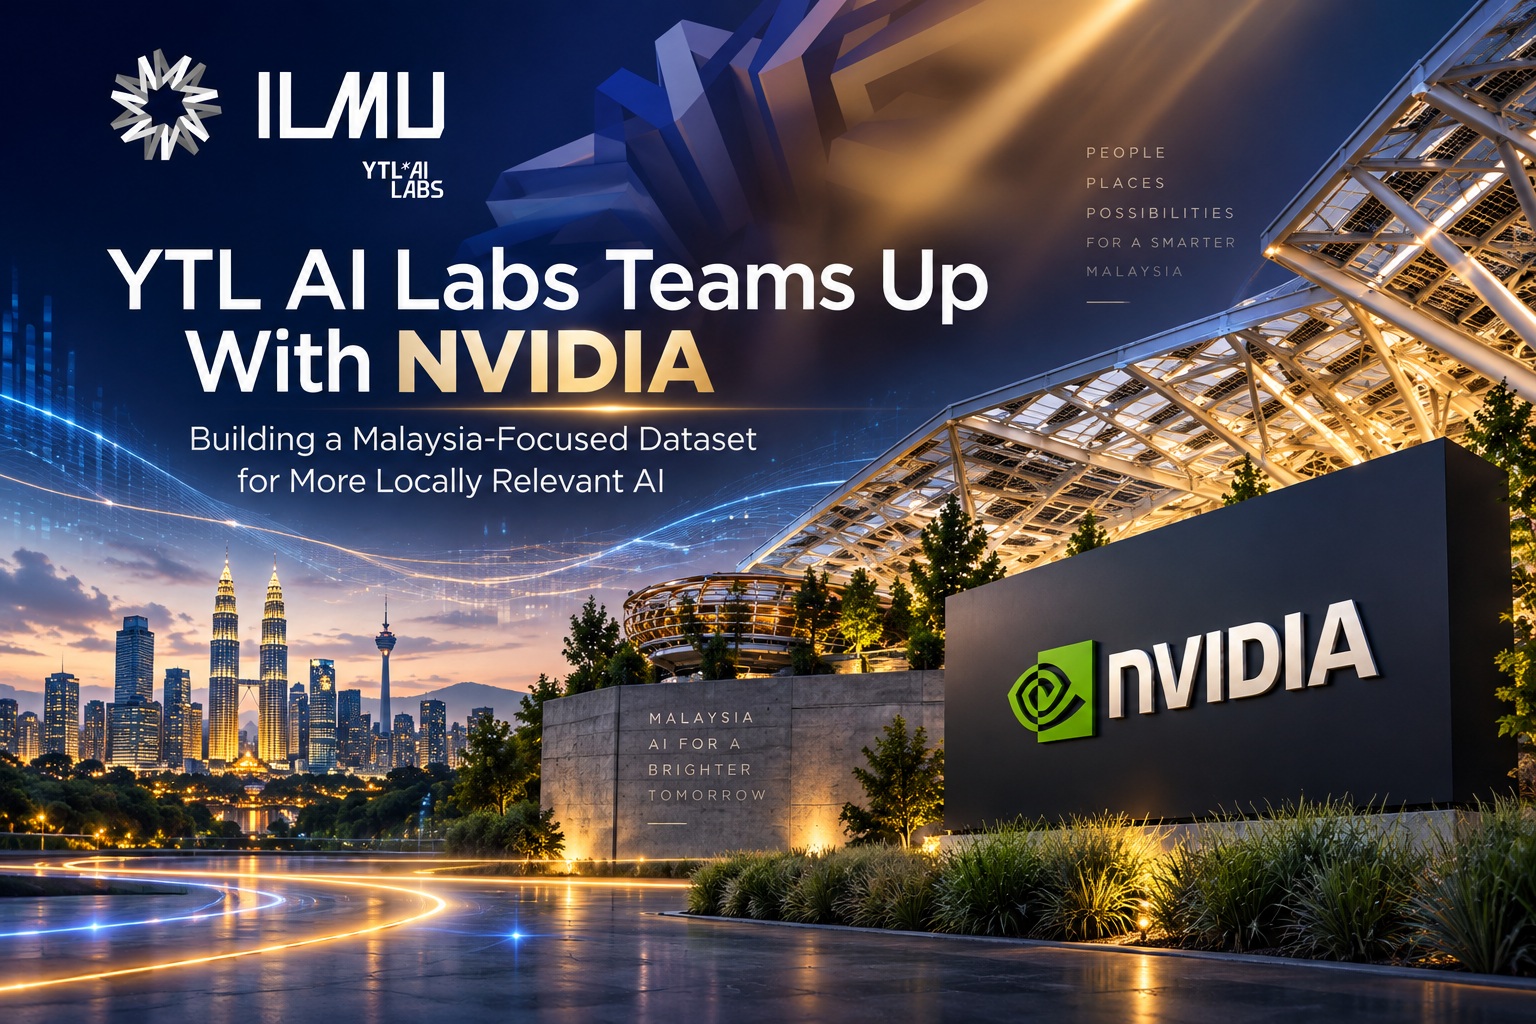
YTL AI Labs is taking another step in Malaysia's sovereign AI push with the launch of Nemotron-Personas-Malaysia, an open dataset created in collaboration with NVIDIA. The dataset contains around 1.35 million synthetic personas designed to help developers, researchers and organisations build and test AI systems that better reflect Malaysia's population, languages, cultures and socioeconomic diversity.
Rather than relying on generic global datasets, Nemotron-Personas-Malaysia is built using Malaysian demographic and labour statistics. YTL AI Labs says the dataset is based on approximately 150,000 base records derived from official sources including the Department of Statistics Malaysia, OpenDOSM, MyCensus, eStatistik and national labour-force publications. Importantly, the personas are synthetic and are not intended to represent or identify real individuals.
Why Local Context Matters for AI
One of the biggest challenges with AI development is that models can perform well in broad international settings while still struggling with local context. Malaysia is particularly diverse, with different ethnic groups, languages, religious backgrounds, regions, occupations and ways of expressing the same idea.
An AI system trained primarily on global or Western data may understand English well but still fail to recognise how Malaysians naturally phrase questions, discuss finances, communicate with public services or switch between languages. That becomes a problem when the system is being used in customer service, banking, government, healthcare, education or other areas where local understanding matters.
Nemotron-Personas-Malaysia is intended to help close that gap by giving AI developers a much richer way to simulate Malaysian users during testing and development.
1.35 Million Synthetic Personas Built From Official Statistics
The dataset contains about 1.35 million hypothetical individuals, each generated using probability distributions derived from Malaysian demographic information. Rather than simply creating random names and profiles, the system uses statistical relationships from official datasets to construct more realistic combinations of characteristics.
Each persona can include information such as age, gender, ethnicity, occupation and geographic region, alongside personality characteristics based on the OCEAN model. OCEAN refers to five commonly used personality dimensions: openness, conscientiousness, extraversion, agreeableness and neuroticism.
YTL AI Labs says each persona contains 39 individual data fields, giving developers enough detail to simulate a wide range of users and situations.
Because the records are generated rather than copied from real people, the dataset is designed to provide demographic diversity without exposing personally identifiable information.
A Broader Representation of Malaysia
A particularly important aspect of the project is the range of communities represented. Nemotron-Personas-Malaysia covers major ethnic groups including Malay, Chinese, Indian, Kadazan-Dusun, Bajau, Murut, Iban, Bidayuh and Melanau, alongside different religious, professional and regional backgrounds.
That wider representation is important because national AI systems should not perform well only for the largest or most visible population groups. A chatbot that understands users in Kuala Lumpur but struggles with users from Sabah or Sarawak is not truly representative of Malaysia.
The same applies to occupations and socioeconomic circumstances. A university student in Penang, plantation worker in Sabah, engineer in Johor and small-business owner in Kelantan may all interact with an AI system very differently. Synthetic personas give developers a way to test those differences before deploying systems at scale.
Bahasa Melayu Takes Centre Stage
Nemotron-Personas-Malaysia is also notable for being the first dataset in NVIDIA's Nemotron-Personas collection to use Bahasa Melayu as its primary language.
That matters because language is one of the clearest expressions of local context. AI systems may technically support Bahasa Melayu while still performing inconsistently when dealing with local phrasing, informal expressions or Malaysian communication patterns.
Having Bahasa Melayu at the centre of the dataset gives developers a stronger foundation for evaluating whether models genuinely understand Malaysian users rather than merely translating from English.
NVIDIA's wider Nemotron-Personas collection already includes country-focused datasets for markets such as the United States, Japan, India, Singapore, Brazil, France, South Korea, El Salvador, Vietnam and Belgium. Malaysia now joins that growing collection with a dataset specifically structured around its own population.
Useful for Testing Customer Service AI
One of the most obvious applications is customer service. A company could use the synthetic personas to test whether an AI assistant performs consistently when interacting with customers of different ages, states, occupations or language backgrounds.
For example, an older user from Perak may explain a problem differently from a younger user in Kuala Lumpur. Someone comfortable with formal Bahasa Melayu may phrase questions differently from a user who mixes Malay and English in the same sentence.
Testing against a larger variety of simulated users can help organisations identify weaknesses before the system reaches real customers. Instead of relying on a small internal test group, developers can evaluate thousands or millions of different hypothetical profiles.
That does not replace real-world user testing, but it can significantly expand the range of scenarios examined during development.
Banks Could Use It to Test Financial AI
Financial institutions could also benefit from the dataset. AI systems are increasingly being used to answer banking questions, assist with budgeting, classify customer needs and support digital onboarding.
The challenge is that financial behaviour and communication vary significantly between individuals. A young professional asking about investments may use completely different language from a retiree asking about savings, while a small-business owner may describe cash-flow problems differently from a salaried employee.
Synthetic personas can help banks assess whether their AI systems understand these differences and whether responses remain appropriate across demographic groups. They may also help identify cases where a system unintentionally performs better for one type of user than another.
That becomes increasingly important as AI moves closer to financial decision-support systems.
Government Services Could Benefit From More Representative Testing
Government agencies are another obvious use case. Digital public services are intended to serve everyone, so AI systems deployed in those environments need to work across a much broader demographic range than most commercial applications.
A Malaysia-focused persona dataset could help agencies test whether digital assistants or public-service platforms behave consistently across different regions, age groups and language preferences.
Researchers could also use the dataset to examine whether certain AI systems respond differently depending on demographic characteristics. That kind of evaluation can help identify potential bias or accessibility problems before they become embedded in public-facing systems.
The key advantage is scale. Instead of manually creating a small group of test personas, researchers can work with a much larger synthetic population that reflects national statistics more closely.
Synthetic Data Helps Protect Privacy
Using synthetic personas also addresses an important privacy challenge. Training and testing AI with real personal data can create significant legal and ethical concerns, particularly when datasets contain sensitive demographic or behavioural information.
YTL AI Labs says the personas in Nemotron-Personas-Malaysia cannot be linked back to real individuals. The records are generated using probability distributions rather than copied directly from actual citizens.
That allows developers to work with realistic demographic patterns without needing access to identifiable personal information. Synthetic data is increasingly being used for exactly this reason: it can preserve useful statistical characteristics while reducing the privacy risks associated with real records.
Of course, synthetic data still needs careful design. If the underlying statistics are incomplete or biased, the generated personas may inherit those limitations. Developers therefore still need to understand where the source data comes from and what it does or does not represent.
Part of YTL's Sovereign AI Strategy
Nemotron-Personas-Malaysia is part of YTL's wider sovereign AI initiative, which also includes the company's ILMU model family and YTL AI Cloud infrastructure.
The broader idea behind sovereign AI is that countries should not depend entirely on foreign models, infrastructure and datasets when building systems that affect local citizens. Global AI technologies can still be used, but local organisations retain greater control over the data, cultural context and priorities that shape the final systems.
YTL AI Labs CEO Foong Chee Mun has argued that AI development should not be judged only by model size. A large model may be technically impressive, but it is far less useful locally if it does not understand the society it is intended to serve.
That is where a dataset such as Nemotron-Personas-Malaysia becomes important. It helps developers combine global AI platforms with local demographic context rather than forcing Malaysian applications to rely entirely on generic international assumptions.
Global Technology, Local Understanding
The collaboration with NVIDIA also demonstrates that sovereign AI does not necessarily mean building every part of the technology stack domestically. Malaysia can still use global infrastructure and AI technology while developing local datasets, models and services that better reflect national needs.
This hybrid approach may be more practical than attempting to recreate every piece of the AI ecosystem independently. Companies such as NVIDIA provide powerful compute platforms and development tools, while Malaysian organisations can focus on the parts that require local expertise.
That includes language, cultural norms, population structure, business practices and regulatory requirements.
The result could be AI systems that benefit from global technological progress without losing the local understanding needed to function effectively in Malaysia.
Publicly Available Through Hugging Face
Nemotron-Personas-Malaysia is being made openly available through Hugging Face, giving developers, researchers and enterprises access to the dataset for their own projects.
Open availability is important because it allows smaller organisations and academic researchers to benefit alongside larger companies. A Malaysian startup developing an AI customer service platform can access the same base dataset as a large financial institution or university research team.
It can also encourage experimentation. Developers may discover applications beyond those originally envisioned by YTL AI Labs, particularly as synthetic personas become more widely used in model evaluation, simulation and agent testing.
The open release therefore makes the project more than an internal YTL initiative. It becomes part of the wider Malaysian AI ecosystem.
Why This Could Matter for Malaysian AI Development
Malaysia-focused AI requires more than simply adding Bahasa Melayu support to a global model. Language is important, but so are culture, geography, socioeconomic differences and the many ways people communicate depending on background and circumstance.
A dataset representing those differences gives developers another tool for evaluating whether their systems actually understand Malaysian users.
It could also help move AI testing away from one-size-fits-all benchmarks. A system might perform extremely well on international evaluations while still struggling with local users. Malaysia-specific datasets provide a way to measure those gaps directly.
Over time, that could help raise the quality of locally deployed AI across banking, public services, customer support, education and many other areas.
Final Thoughts
The launch of Nemotron-Personas-Malaysia represents an interesting step toward building AI systems that are not only powerful, but genuinely relevant to the people using them. With 1.35 million synthetic personas, 39 data fields per profile and demographic coverage drawn from official Malaysian statistics, the dataset gives developers a much richer foundation for local testing.
Its Bahasa Melayu-first approach is particularly significant, as is the effort to represent communities across Peninsular Malaysia, Sabah and Sarawak rather than treating the country as one homogeneous population.
The project also shows what sovereign AI can look like in practice. Malaysia does not necessarily need to build every AI technology from scratch. It can work with global companies such as NVIDIA while maintaining control over the local datasets, context and priorities that determine how those technologies are applied.
The biggest AI model is not always the most useful one.
For Malaysian users, the more important question may eventually be whether the AI actually understands who we are, how we communicate and the context in which we live.






Comments 0